

As social impact organizations increasingly turn to AI, the available tools are evolving faster than most organizations can navigate. For nonprofits operating with small technical teams, it can be especially difficult to compare and select the best AI tools for their needs.
After years of embedding engineering teams with high-impact organizations—and co-designing AI systems alongside them—The Agency Fund has developed a perspective on this challenge. Drawing on partnerships with more than 30 nonprofits across Asia, Africa, and Latin America, we recently conducted a mapping exercise evaluating more than 50 tools.
This blog shares the results: a set of default tool recommendations for NGOs with small technical teams building out a modern technology stack. Our recommendations have been developed in collaboration with data.org, Fast Forward, and IDinsight.
No single tool will work for every organization and context, but the goal is to provide vetted defaults that help social impact organizations get started. While primarily intended for organizations with understaffed engineering teams, the mapping may also help more mature organizations building new components of their technical stack. If you already have a strong engineering team and a modern stack, there are better resources for you. This is for the rest.
How we evaluated the tools
For small tech teams, the time and cost of evaluating tools is often a major bottleneck. Teams can spend months comparing platforms and testing integrations before anything reaches users. Good defaults help organizations launch quickly, then adapt or replace tools over time if needed.
Our mapping rated tools using three criteria, taking into account the operational realities facing small engineering organizations in the social sector. Tools were rated on a three-tier scale within each criterion:
Reliability: Does the tool hold up in low-connectivity environments and with non-specialist operators?
Sustainability: Is the tool supported by an active community and strong documentation, with a high likelihood that key social-sector use cases have already been addressed?
Cost: What is the tool’s total cost at scale, including setup time and ongoing maintenance, along with cost-reducing options such as free tiers and open-source paths?
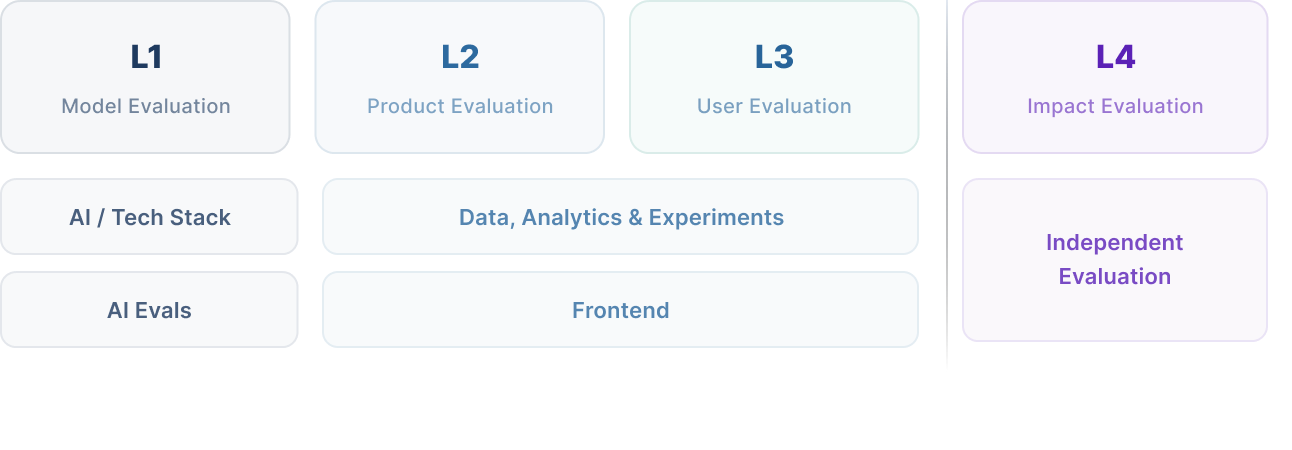
The mapping also aligns with the four-level framework for AI evaluation, particularly those first three levels: evaluating AI model performance (L1), product performance (L2), and changes in users’ thoughts and behavior (L3). Broader impact evaluations (L4) fall outside the scope of this mapping, but remain essential: the goal is not simply to deploy effective AI tools, but to understand whether they are generating measurable improvements in users’ lives.
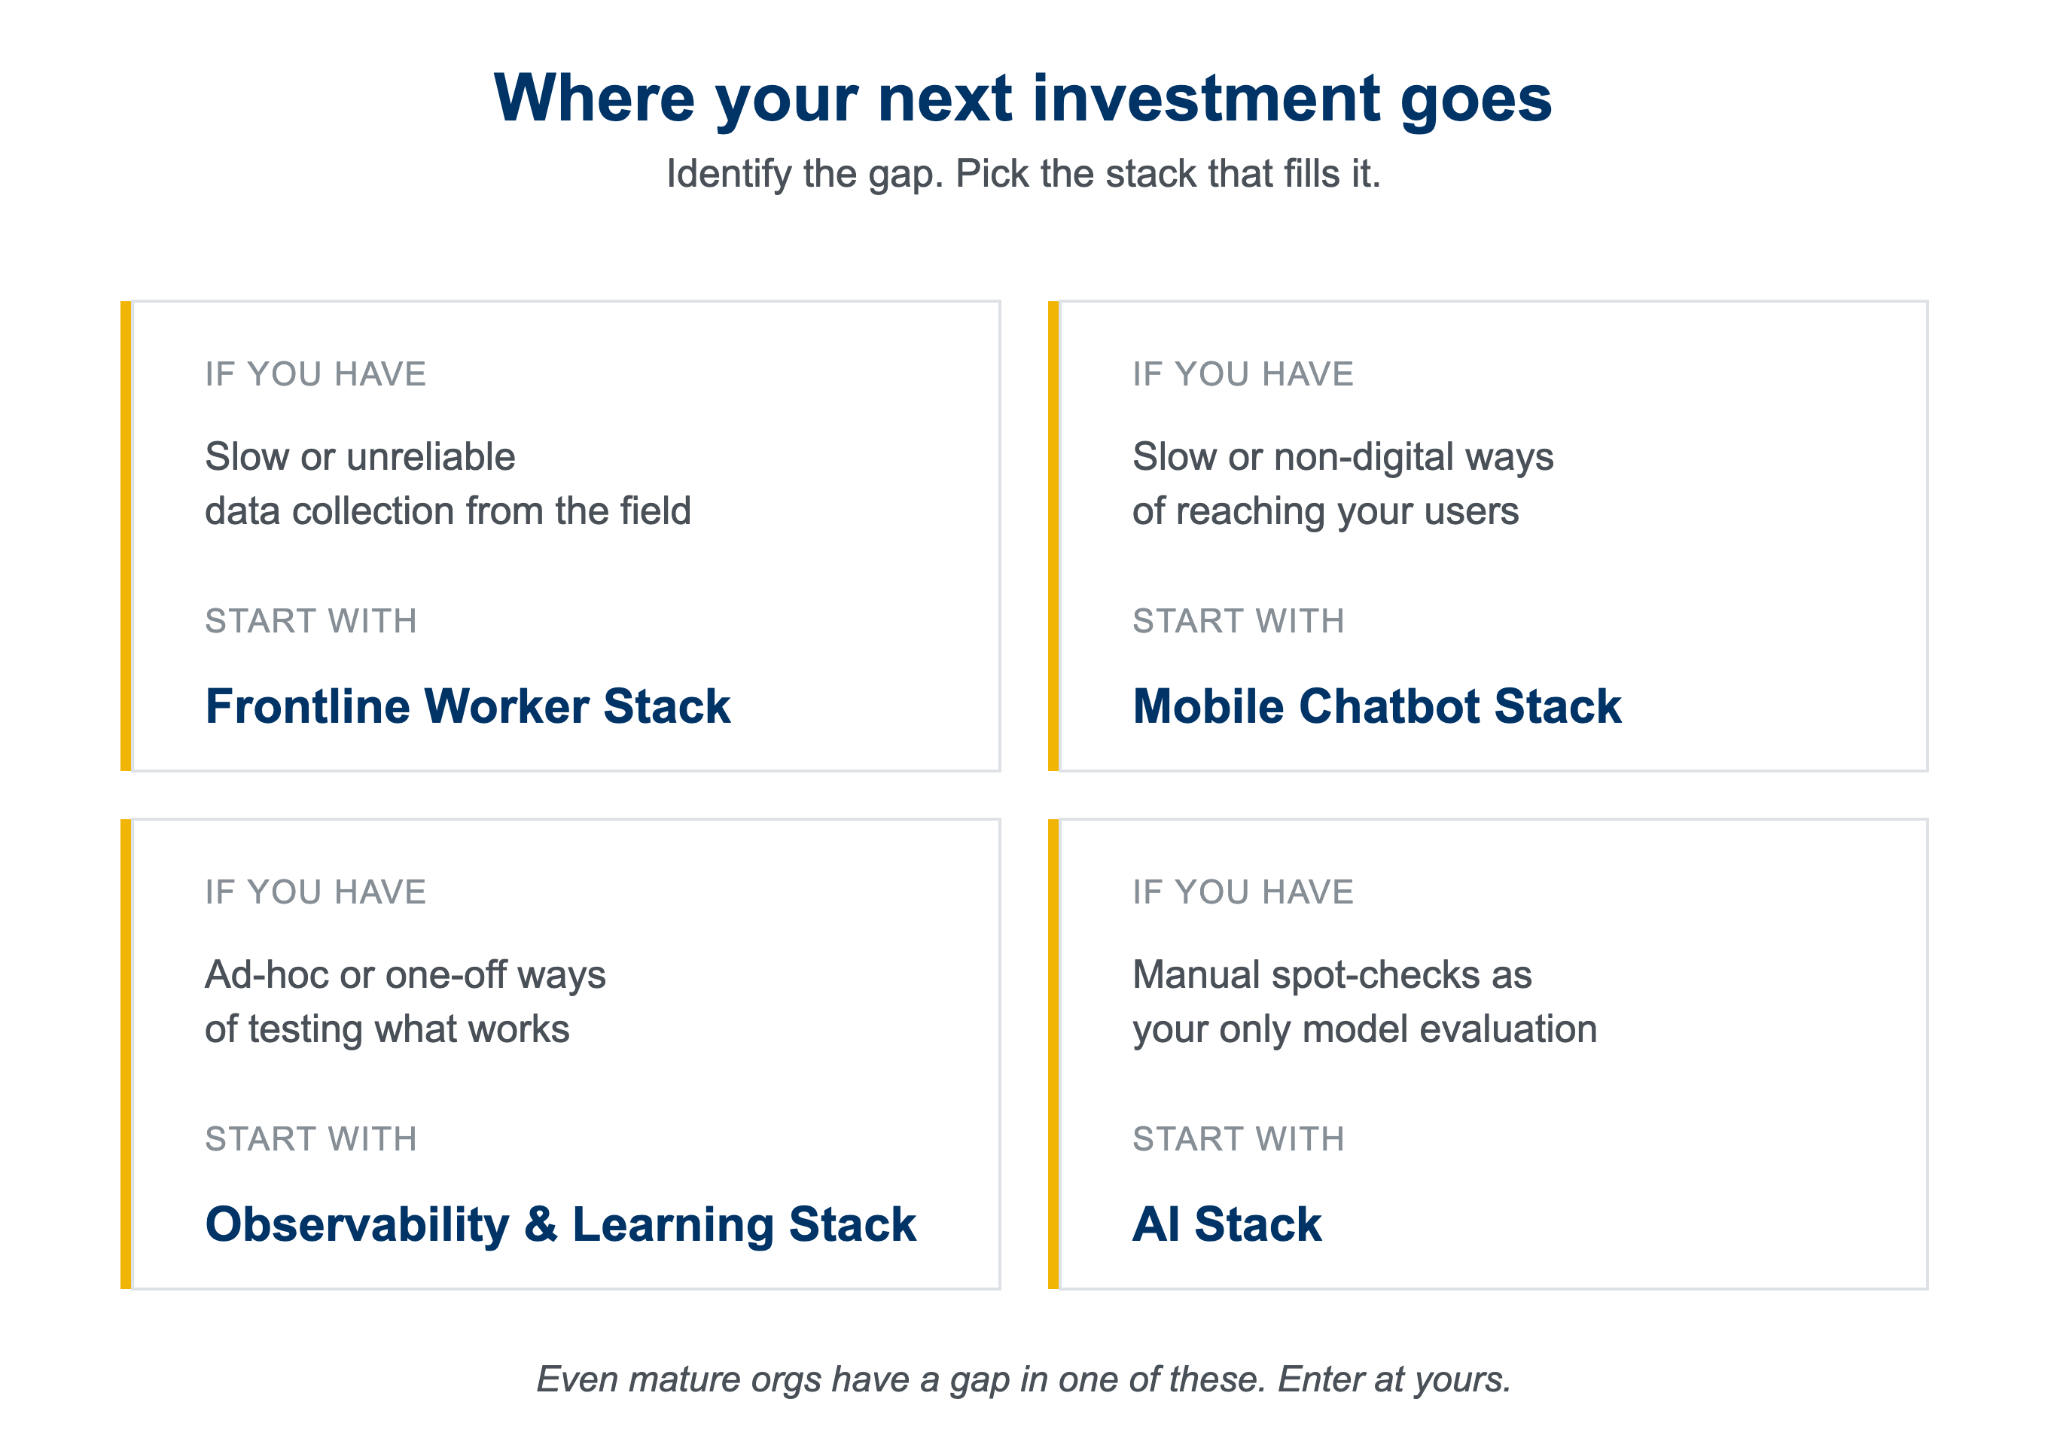
Most organizations will not need to build their entire technology stack at once. The goal of this mapping is not to encourage adoption of every tool below, but to help organizations identify investments that can unlock progress. Where are your operational bottlenecks? For some organizations, it might be data infrastructure or frontline data collection; for others, mobile chat delivery or experimentation capacity.
Our default tech stack
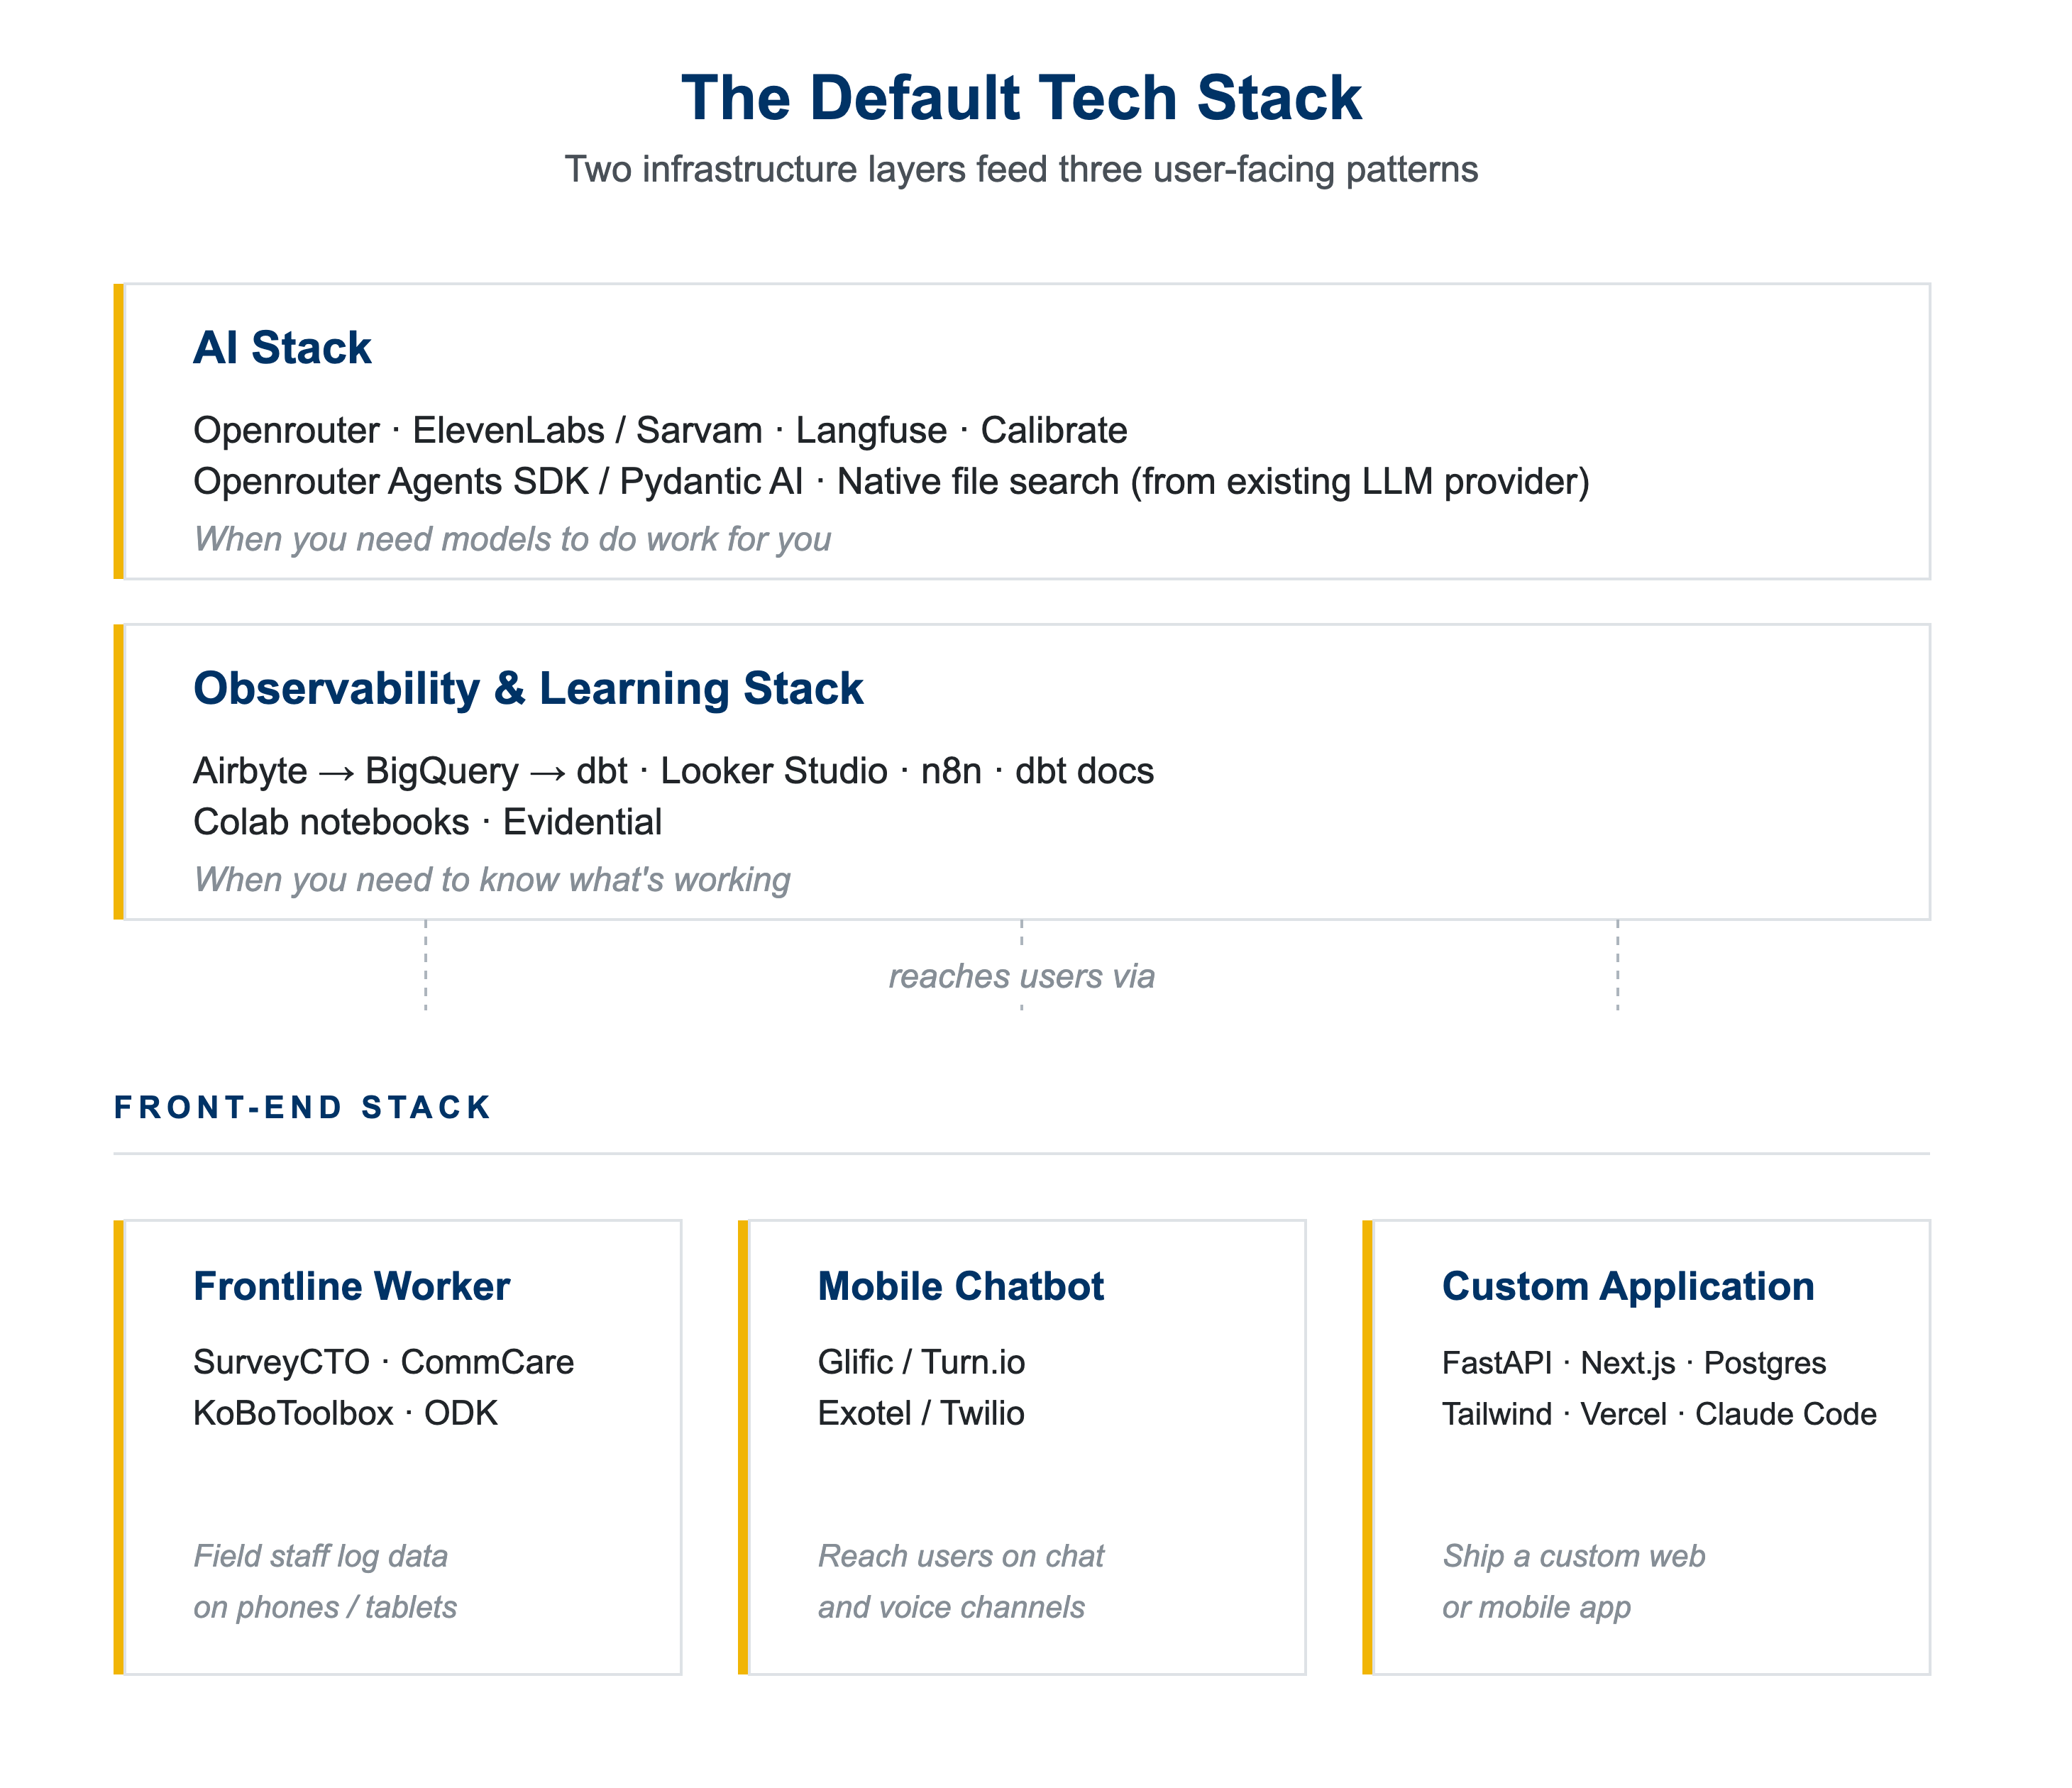
We evaluated tools across three layers of the stack. Below, we provide default recommendations for each layer. Where relevant, we also highlight strong alternatives, emerging tools, and practical heuristics for choosing among tools based on organizational context, use case, and operational constraints. All these tools are either open source, or offer very generous free tiers and if you don’t want to self-host, many tools below have cloud offerings with nonprofit discounts.
The AI Stack
What does it include? Technologies that power AI products, including large language models (LLMs), speech systems, monitoring, evaluation, and retrieval.
LLM gateway
This layer sits between your app and the foundation model providers, letting you switch between model systems (e.g., Gemini, OpenAI, Claude) without rewriting code.
Default: OpenRouter. Avoid locking yourself into a single model. Openrouter provides a unified interface for accessing Gemini, OpenAI, Claude, and other models.
Alternative: LiteLLM
When to deviate: If you are already committed to a specific model provider and want to avoid the additional abstraction.
Additional: Generally, this link will guide you through different LLMs’ performance across parameters like creative writing, coding etc. For breadth across African languages, benchmarks like AfroBench and Masakhane give better granularity and for Indic languages, AI4Bharat’s MILU benchmark captures them better. If your domain is niche enough, you will generally need to find or produce your own small evaluation set: a few dozen real, natively written queries in the target language, each paired with a native-speaker or expert reference answer or a scoring rubric.
LLM monitoring and evaluation
Tools that record what your AI is saying and doing, so you can spot when it starts going wrong. These tools can also be used for ad hoc evaluation of model performance in target languages or domains.
Default: Langfuse. Helps teams monitor model calls and debug regressions.
Speech systems
Tools that turn speech to text (STT) and text to speech (TTS), for chatbots that talk and listen.
Defaults: ElevenLabs or, for Indic languages, Sarvam.
Alternative: Gemini/Google Cloud STT & TTS
Speech evaluation
Tools that help you find the best speech-to-text and text-to-speech models for your target users across different languages and domains.
Default: Calibrate. Find the best audio model for your dataset across providers.
Alternatives: Maxim
Agent builders
Frameworks for building AI agents that take multi-step actions (e.g., searching, fetching information, calling other tools) instead of just answering one question at a time.
Defaults: OpenRouter Agents SDK or Pydantic AI (model agnostic).
Alternatives: Claude Agents SDK, OpenAI Agents SDK.
Heuristic: If staying flexible across AI providers matters more than getting every feature out of the box, look at OpenRouter Agents SDK or Pydantic AI. It works with multiple AI providers (Gemini, Claude, OpenAI), so you’re not tied to one. The trade-off: fewer built-in features than provider-specific SDKs.
Vector database
These tools store the documents your AI needs to reference, so it can pull the right context when answering questions about your data.
Default: Native file search from your LLM provider. OpenAI, Gemini, and Claude all offer built-in file search APIs. Upload documents, ask questions, and retrieve answers without managing a vector database or embedding and maintaining a pipeline. For most organizations, this is the easiest place to start.
Alternatives: Weaviate, pgvector (in Postgres).
Heuristic: Your documents and indexes live inside one provider, so switching later means re-ingesting everything. If avoiding lock-in matters more than initial simplicity, use Weaviate or pgvector instead. Use Weaviate to get a simple, managed vector database layer for indexing and retrieval, letting you switch between different models and perform different kinds of retrieval, such as hybrid search, semantic search (exact and approximate), and text search. Use pgvector (in Postgres) if you want greater infrastructure and cost control or custom embedding logic.
The cheapest vector database is often none. If your documents fit in the model’s context window, you can just skip retrieval and pass them in the prompt with caching.
The Observability and Learning Stack
What does it include? Tools that help organizations manage, monitor, and improve AI systems through data pipelines, dashboards, workflow orchestration, analysis, and experimentation.
Data pipelines
This is the plumbing that moves data from wherever you collect it (e.g., survey forms, chatbots, apps) into one place you can analyze.
Default: Airbyte → BigQuery → dbt. A reliable combination for nonprofit-scale data infrastructure. Airbyte handles ingestion from collection tools, BigQuery provides storage, and dbt supports reliable data transformation.
Dashboards
Visual reports that show how your programs are performing across usage, outcomes, or anything else you’re tracking.
Default: Looker Studio. It’s free and tightly integrated with BigQuery.
Alternatives: Metabase for organizations that need self-hosted dashboards or richer drill-down capabilities. Superset is another alternative.
Workflow orchestration
Automation for the tasks your team currently does manually: “when X happens, do Y.”
Default: n8n. A low-code platform that is increasingly accessible for NGOs; it makes it easier to automate operational workflows without extensive engineering effort.
Data catalogs
A searchable index of all the data your organization has, so people can find what exists without asking around.
Default: dbt docs. Many organizations already use dbt and have free access to the catalog.
Ad-hoc analysis
One-off explorations of your data – not regular reports, but specific questions (e.g. “how did this group respond last month?”) that you only want to answer once.
Default: Colab notebooks. Familiar, free, and easy to share across teams.
Emerging: Using Claude with dbt and Postgres MCP has cut down analysis time by roughly 5x in our recent work. Worth experimenting with, if you have the technical bandwidth.
Experimentation
Tools for running A/B tests on your programs: randomly varying what users see, then measuring what works better.
Default: Evidential. The Agency Fund’s open-source A/B testing platform, built specifically for nonprofits experimenting at scale.
Alternatives: Growthbook, Posthog.
The Front-End Stack
What does it include? Tools that shape how users see and experience your AI products. Most nonprofit products reach users through one of three delivery models: frontline worker services, mobile chatbots, or custom applications built by small teams or technical founders.
Frontline Worker Services
For when field staff carry phones or tablets, log data with beneficiaries, and sync it back to your systems – often in low-connectivity and form-heavy contexts. These tools are foundational; most organizations start here.
Default: SurveyCTO. Reliable offline sync, mature form logic, and strong documentation. Works well for most organizations without the higher cost ceiling of CommCare.
Alternatives: CommCare for mature case management and longitudinal tracking. KoBoToolbox when budget is the primary constraint. ODK for organizations with the engineering capacity to self-host.
(Note: The Agency Fund has built lightweight tools to integrate SurveyCTO and CommCare data into organizations’ data systems with minimal effort. Reach out if your data collection layer is in place, but the integration layer is not.)
Mobile Chatbot Services
These tools reach users directly on WhatsApp, Telegram, or by phone with no frontline worker in the loop– for when you’re ready to deliver services at scale, not just collect data.
Defaults (heuristic): Use Glific if cost or NGO-community fit matters most, or Turn.io if overall experience matters more. Glific can be self-hosted (lowest cost, requires engineering capacity) or used via their hosted service. Both integrate directly with BigQuery, making it easier to analyze user interactions and chatbot service performance.
For voice and phone systems: Twilio for global deployments; Exotel for India-focused deployments.
Custom applications (for 1- or 2-person engineering teams)
When you need a web or mobile app of your own – built by your team, designed for your specific workflow.
(Note: These tool recommendations for custom applications aren’t intended for engineering teams of three or more. There are better resources for that audience. But if you’re a solo technical founder or a very small team building a custom application, the stack below is what we’d start with. Together, these tools provide a strong balance between flexibility and ease of use, with documentation and community support that make them practical for small teams.)
Back end: FastAPI. Handles requests, databases, and APIs.
Front end: Next.js. Renders the user interface, fast. Alternative: Cloudflare, highly secure and free to get started.
Database: Postgres (with pgvector). Stores everything, including vector embeddings if you’re doing AI work.
Styling layer: Tailwind. Makes it easier to build polished interfaces without extensive custom CSS.
Deployment platform: Vercel. One command to put your app online. Alternative: Railway.
AI coding agents: Claude Code (default). Alternative: Cursor. The capacity bar for building custom apps has fallen dramatically. Today, a semi-technical founder working with a coding agent can often ship products that previously required a dedicated three-person engineering team.
Hard-won lessons from the field
Over the course of deploying and evaluating 50+ tools, five broader lessons emerged about how organizations can get the most value from AI systems.
Standardize product metrics before building analytics. How long should it take to know whether your product is working for users? Organizations often jump into ad hoc analytics before defining their user funnel metrics. Months later, different teams calculate “engagement” in different ways, leaving leadership with multiple answers that are all defensible but not comparable. Instead, start with a small set of standardized user metrics, get leadership sign-off, and build the automated pipelines and dashboards to track them – then you can iterate and add complexity.
Build evaluation systems before you scale. How long should it take to catch a regression in AI system performance? Many organizations launch AI interventions without evaluations or observability tooling in place. Manual spot-checks can work at low volume, but they break down as usage grows, making retroactive evaluation infrastructure costly and disruptive. Instead, start with a curated golden dataset and connect an observability tool (our default is Langfuse) before launch.
Make experimentation a habit. Many organizations treat each experiment (or A/B test) as a one-off project, rebuilding processes from scratch every time. Over time, design quality suffers, and key aspects – like design variations, test prioritization, and internal buy-in – become harder rather than easier. Instead, embed experimentation as a recurring practice, supported by low-friction tooling, with involvement of leadership and your delivery team. The barrier is rarely technical; it’s cultural and operational. But the returns to effective learning compound over time.
Recognize gaps, work around them, and share what’s missing. Some problems still do not have clean, off-the-shelf solutions – including data catalog interfaces for non-technical users, identity resolution (when registration forms are handwritten or inconsistent), and automatic tracking of metrics across heterogeneous data sources. In these cases, adopting enterprise tools designed for large tech companies often makes the problem worse. Instead, be honest about the gaps you identify, work around them for now, and share the issues publicly so that the nonprofit software ecosystem can build better solutions over time. These are exactly the kinds of challenges that The Agency Fund is focused on.
Build only what serves your mission. AI tools are making development streamlined, and support for nonprofits is growing. But every new feature you build must be maintained by your team and navigated by your users; more functionality does not always generate more value. Before you build, ask: does this serve our beneficiaries, and do we have the capacity to maintain it?
Where this is heading
This mapping is a living document. The ecosystem shifts constantly as new tools emerge, older ones are acquired, prices change, and capabilities expand. Our recommendations will continue to evolve alongside it.
We are watching several trends particularly closely: how non-technical users interact with data in the next generation of tooling, how the capacity bar continues to fall for nonprofits building their own products, and how the gap between “tools for big tech” and “tools that fit an NGO” continues to shape what is actually usable in our sector.
As our view sharpens, we will continue updating the map and sharing what we learn.
Want to talk through your stack? If these challenges sound familiar, we’d love to talk. Book a free 30-minute consultation with our team. We’ll help you identify your gap and choose a practical starting point.
Questions or feedback? Email tech@agency.fund or comment below.
Browse the tools: You can also browse the full validated tools database, which includes all 50 tools we evaluated, along with ratings and implementation notes.
We are going through this process right now at choosing a open and affordable stack as opposed to a bespoke custom solution from a software dev team. We decided on using kobotoolbox self hosted with frappe to run custom app for inventory management
Since we did start with the idea for a bespoke app but moved on to open source, it feels like we are letting go of a lot of useful features for the people on the frontline
For example, in a bespoke app we could add a module to OCR a identity card and take the name and age, or build them a seperate menu where they can track their inventory
But on Kobo, they have none of that, they don't even get a full view, responses are not even searchable
To begin with these solutions looks affordable and will get the job done, and the above was just one example, there a lot of features we had to let go
So what do you suggest in these situations, what is a solution that won't break the bank but also provide the really useful features people want
Also, what are you suggestions for hosting the custom apps being built?